The model is the improviser; memory is the constitution
On why AI agent memory has become an engineering discipline in its own right — and why bigger context windows don't solve it
The most consequential change in AI agent design this year is not a new model release. It does not have a product keynote or a benchmark leaderboard all to itself. It is the realization, arriving in production systems and now documented in at least a dozen papers and frameworks, that an agent's memory is an engineered object — and that engineering it badly makes a capable model structurally unreliable.
That shift deserves more attention than it gets.
When brilliant is not enough
Imagine a consultant who is extraordinarily good at reasoning: she can follow a complex brief, spot inconsistencies, propose elegant solutions. There is one problem. She does not remember what you told her last week. She remembers everything you said this session, but whether the priority you mentioned three conversations ago has changed, whether the constraint you added yesterday supersedes the one from Tuesday, whether a particular decision was hers or yours — that is all gone.
You would not say this consultant is bad at her job. You would say she cannot be trusted across time.
That is the precise structural problem with a language model that treats memory as a growing transcript. The model can reason over whatever reaches its context window. It has no authority over what reaches it, no judgment about which memories are authoritative, and no mechanism to reconcile contradictions. A user who moves cities, changes roles, or revises a preference silently contaminates every future response if that old fact persists.
The apt framing is architectural: the model is the improviser; memory is the constitution. The constitution determines what reaches the improviser, which part of the past governs the present, who may alter it, and whether an old error returns as a fresh instruction.
Context capacity is not memory governance
Bigger context windows made the problem seem less urgent. They did not make it less real.
More capacity still does not tell a system which of two conflicting user statements is more recent, whether a completed task should influence a future one, or whether a piece of text came from the user, from a tool, or from the agent's own speculative summary. These are questions of governance, not capacity. An undifferentiated transcript — even a very long one — is an archive without an archivist.
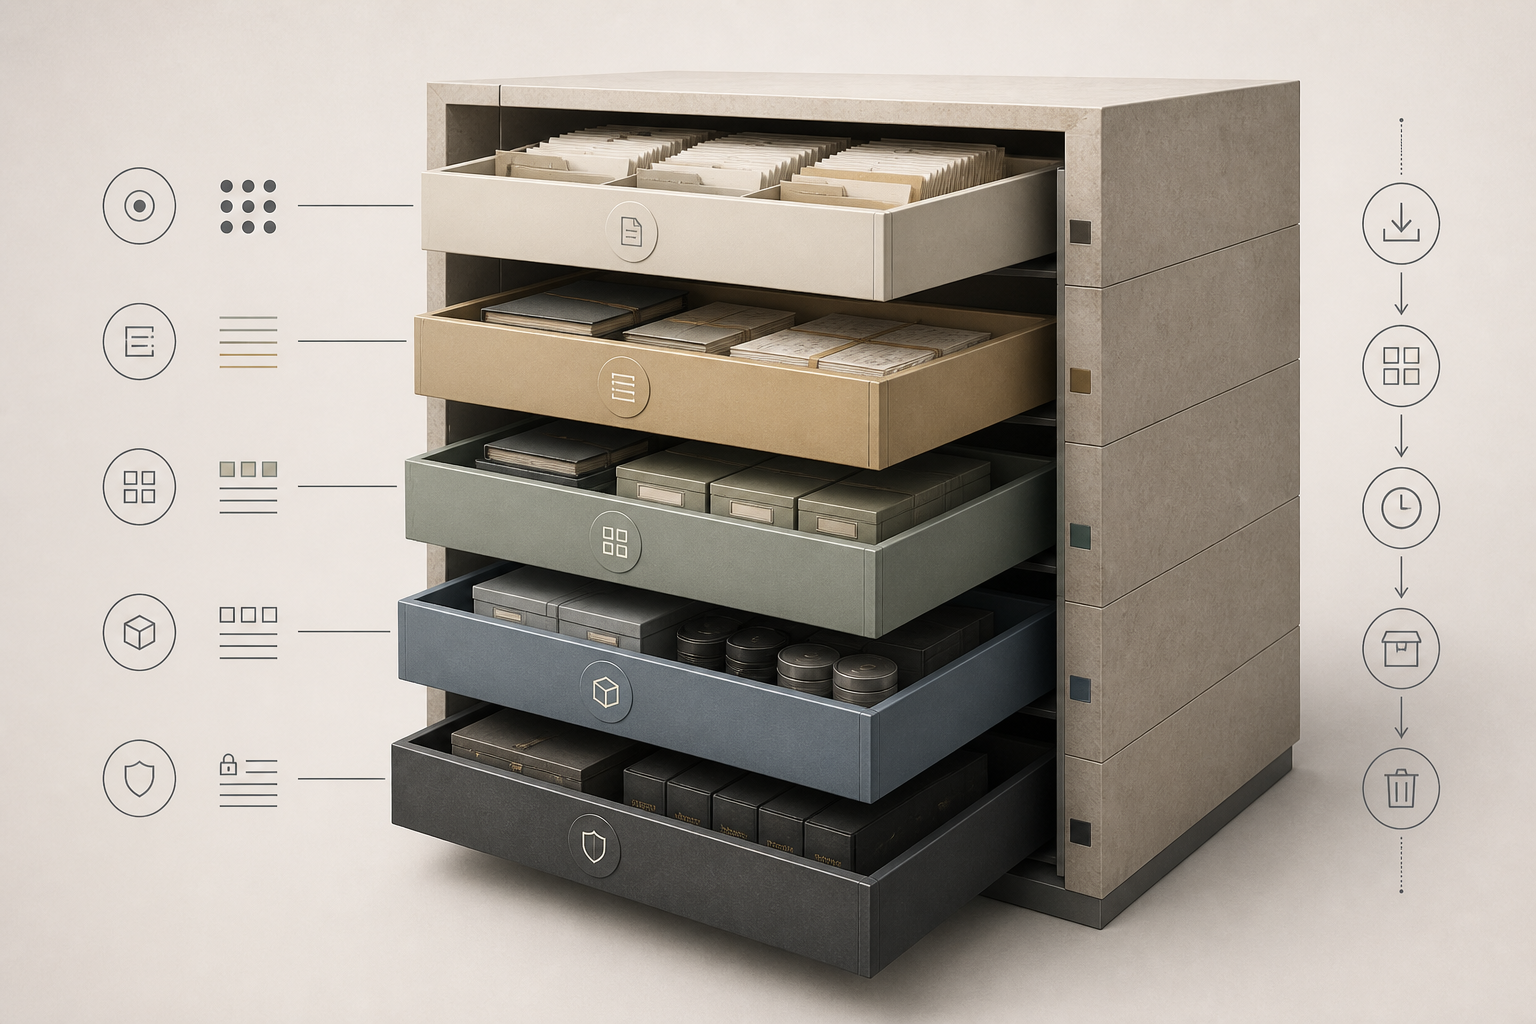
The architectural response that has emerged across production systems separates at least five distinct jobs.
Working memory holds what must always be present: current goals, identity, safety rules, a small set of decisive facts. Letta's memory blocks are the clearest public example — structured text persisted directly in the prompt at all times. The trade-off is explicit: it prevents retrieval misses, but has a hard size budget.
Archival memory holds the much larger past and retrieves a small slice on demand. Most implementations combine vector embeddings with keyword search and metadata filters. The combination matters: semantic similarity alone is insufficient when "the billing issue" is semantically close to two different customers' cases, while an entity name and a timestamp decide which one is relevant.
Scoped memory attaches attribution to the record. User, session, agent, project, organisation — these are isolation boundaries, not implementation trivia. A multi-agent workflow without attribution boundaries is a very efficient machine for laundering an agent's inference into a user statement.
Memory type marks the difference between an episode ("this happened"), a semantic fact ("this is generally true"), and a procedural rule ("this is how I should work"). A coding assistant that needs to remember a team's test command needs procedural knowledge. Treating all memory as a flat semantic blob loses that distinction.
Finally, lifecycle management: what to write, how to consolidate it, how to resolve a contradiction, when to decay it, and how to delete it. This layer is where a usable memory actually diverges from an archive. It is also the hardest to get right, because the failure modes are subtle. A memory that was accurate six months ago and is now wrong is not absent; it is dangerous.
What the benchmarks show
Three benchmarks now anchor the evaluation conversation. LoCoMo tests multi-session conversational recall and reasoning. LongMemEval provides 500 questions across six categories including knowledge updates, temporal reasoning, preferences and cross-session recall. BEAM is designed for settings at 1M and 10M tokens, where replaying the entire past becomes economically implausible.
They test related but different things. A high Recall@5 score says relevant evidence entered the top five retrieved results; it says nothing about whether the answering model used it correctly. An LLM-judge score depends on the prompts given to both the answerer and the judge. Before any headline number becomes a claim, a production system needs to fix its model versions, embedding models, prompts and failure-accounting convention.
Mem0's July 2026 report is the strongest available evidence for the practical importance of memory architecture. It reports 92.5 on LoCoMo, 94.4 on LongMemEval, 64.1 on BEAM-1M and 48.6 on BEAM-10M, using roughly 6.7–6.9K tokens per retrieval. A useful small warning: Mem0's own GitHub README gives slightly different LoCoMo and LongMemEval figures — 91.6 and 94.8 — a version discrepancy that illustrates exactly why citing a specific release matters more than citing the marketing page.
The design changes behind the numbers are concrete: one-pass additive extraction, entity linking, and fused retrieval combining semantic embeddings, BM25 keyword search and entity matching. The reasonable inference is not that models barely matter. It is that a managed retrieval-and-scope policy can radically outperform an undifferentiated full-history baseline on precisely the temporal and multi-hop questions that make an assistant feel persistent over weeks rather than minutes.
The stronger claim — that memory architecture universally matters more than backbone model choice — still needs a neutral experiment: hold the memory stack fixed across several models, hold the model fixed across several memory stacks, run both on the same real-world workload. That experiment has not been published. As argued in You can switch LLMs. You can't switch agents., the deeper architectural choices in an agentic system carry far more lock-in than the model underneath.
The metaphors and their limits
Two research systems illustrate what happens when the ambition expands beyond pragmatic retrieval.
MemPalace maps memory into spatial structures borrowed from the classical method of loci: Wings, Rooms, Closets, Drawers. It reports 96.6% LongMemEval Recall@5 with no LLM required at write time. The genuinely attractive part is not the spatial metaphor itself — it is that deterministic, verbatim-first local storage makes writes cheap and memory inspectable. A published critical analysis of MemPalace is worth reading precisely because it is honest: the headline result likely owes more to verbatim storage, the chosen embedding model and ordinary metadata filtering than to anything uniquely architectural about the palace metaphor. That is not a dismissal. It is a reminder to distinguish a useful organizational interface from a demonstrated causal mechanism.
ZenBrain goes the other direction: seven layers, fifteen neuroscience-inspired mechanisms including confidence propagation, reconsolidation, and layered retrieval. Its preprint reports detailed ablations and explicitly admits where its own results fall short — BM25 wins aggregate LoCoMo F1 in one comparison, synthetic traces underpin part of the evaluation. Its most valuable contribution may be the conceptual one: memory systems need explicit update rules and controlled forgetting, not merely a vector collection that only ever grows. Independent replication would significantly strengthen its broader claims.
Production has already settled some questions
There is no single winning memory architecture in production. What Letta, LangGraph and Mem0 share is a design principle rather than an implementation: reserve scarce prompt space for the non-negotiable present, and make the larger past queryable, scoped and revisable.
Letta explicitly warns that concurrent block writes can overwrite one another — a concurrency failure mode that has nothing to do with AI and everything to do with distributed systems basics. LangGraph separates thread-level state from durable, namespaced long-term documents and describes background memory formation as a latency-saving option, not a default. Mem0 combines scoped fact storage with hybrid retrieval. These are different bets on where the hard problems sit.
For any system that runs continuously — a personal assistant, a research agent, a workflow coordinator — the direct lesson is not to mimic any single vendor. It is to make provenance and lifecycle first-class concerns from the start: distinguish what a user said from what an agent inferred; retain source and timestamp; allow a correction to supersede an operational fact without erasing provenance; keep explicit short-lived task state separate from durable preferences; and make stored material inspectable and removable. Nightly consolidation belongs naturally to this lifecycle, provided it does not silently convert an inference into a settled fact.
The open problems
Staleness is harder than absence. A memory that is frequently retrieved is the one that becomes dangerous when it stops being true. Add-only writing avoids destructive overwrites but makes temporal reasoning and supersession essential — and hard. Forgetting is not merely decay: a system may need to cease acting on a belief while retaining its provenance for audit or correction.
Privacy is equally architectural. Persistent memory demands scope boundaries, consent rules, retention limits and deletion pathways that span raw records, summaries and embeddings. In a multi-agent workflow, attribution is a safety mechanism — as When AI colleagues need managers too explores, the question of who is responsible for an agent's output depends entirely on how provenance was tracked. "The user said this," "the tool returned this," and "the agent inferred this" must not collapse into a single undifferentiated record.
There is also a cost discipline that benchmark papers rarely address. Every memory write can require extraction, entity resolution and embedding. Every retrieval adds search, reranking and context injection. Background consolidation reduces foreground latency but introduces consistency problems: what happens to a running agent when the nightly consolidation revises the facts it was acting on?
The benchmark question that actually matters is not Recall@5. It is: can this particular agent remember the right thing, revise it when it is wrong, refuse when the record is too ambiguous to support an answer, and show the user why?
The constitution governs the improviser
None of this diminishes what capable language models do. It changes where the leverage is.
A model with excellent reasoning applied to a corrupted or stale memory produces confident, fluent errors. A model with modest reasoning applied to well-curated, correctly scoped, provenance-tracked memory produces responses that can actually be trusted across sessions. The architecture that feeds the model — what it sees, how old it is, who said it, whether it has been superseded — becomes more determinative of real-world reliability than the next benchmark point on any headline leaderboard.
Memory has become an independent engineering discipline not because models have become unimportant, but because capable models make bad memory more visible. The improviser reveals every weakness in the constitution.
Sources
Mem0
- AI Agent Memory 2026: Progress benchmark report evaluations — Mem0, July 2026. Primary benchmark report with LoCoMo, LongMemEval and BEAM scores.
- Mem0 repository — GitHub. Source of the version discrepancy noted in the article.
- Mem0: Building production-ready AI agents with scalable long-term memory — Chhikara et al., arXiv, 2025. Technical paper on Mem0's one-pass extraction and hybrid retrieval architecture.
Production frameworks
- Memory blocks — Letta documentation. Structured memory blocks, concurrency caveats, and hard size budgets.
- Long-term memory — LangGraph / LangChain documentation. Thread-level state vs. durable namespaced long-term documents.
Research systems & surveys
- Spatial metaphors for LLM memory: a critical analysis of the MemPalace architecture — Dey & Viradecha, arXiv, 2026. Distinguishes organizational interface from causal mechanism in the MemPalace headline result.
- ZenBrain: A neuroscience-inspired 7-layer memory architecture for autonomous AI systems — Bering, arXiv, 2026. Seven-layer proposal with honest ablation results and replication caveats.
- Memory for autonomous LLM agents: mechanisms, evaluation, and emerging frontiers — Survey, 2026. Field overview covering evaluation methodology and open problems.